
Looking for feedback on this type of post
I have started posting Substack Notes on the data, product and AI work I am doing as I do it.
An experiment of designing and building in public.
I can’t decide if a weekly summary of these notes has any value to anybody else or not.
I don’t want to allocate time to manually created these weekly summaries so they are of course generated by a GenAI LLM, based on the notes themselves.
Let me know if these have any value to you and I should continue them, or if they are just spam in your inbox and I shit can the idea.
12 Oct–18 Oct 2026
This week’s notes were all about feedback loops - Claude reviewing its own work against other tools, Juha and Nicolai pointing out where my designs missed the mark, and my own UX experiments failing exactly the way a real user would hit them. The common thread: an idea that looks right in isolation - a KPI calc popup, a dashboard assistant, a shared field description - breaks the moment it meets someone else’s context, scale, or screen.
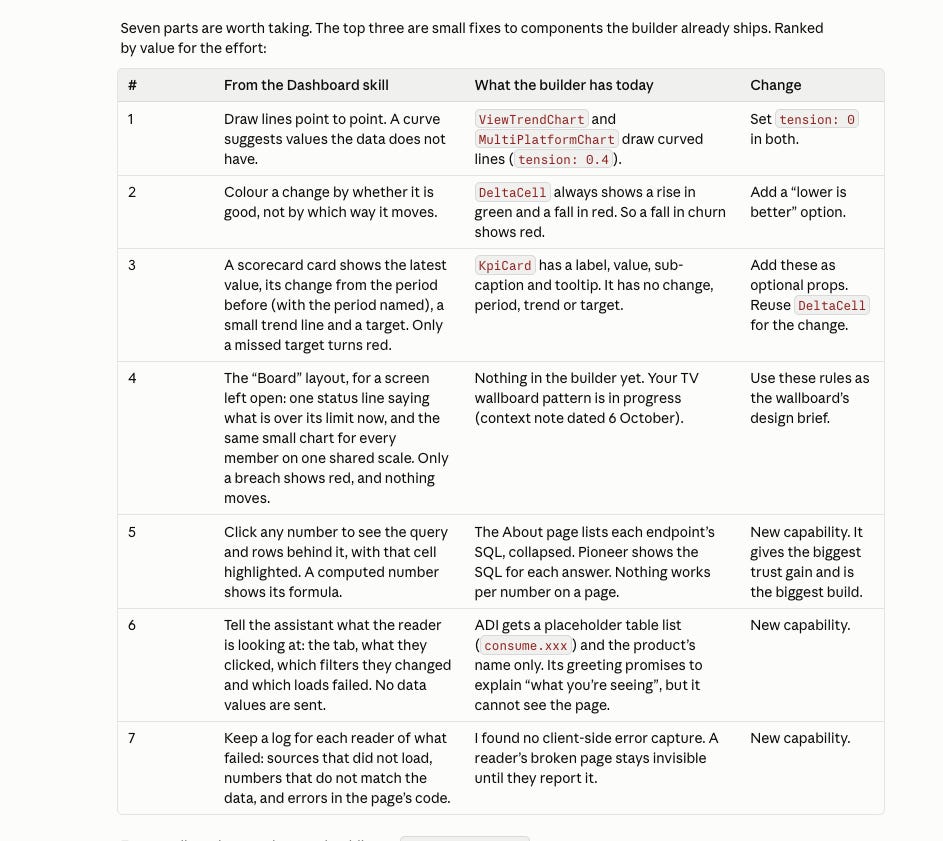
Benchmarking against Claude’s own dashboard skills
Comparing your own capability against another tool’s reference implementation surfaces gaps faster than designing in isolation.
A circuit breaker for agent arguments
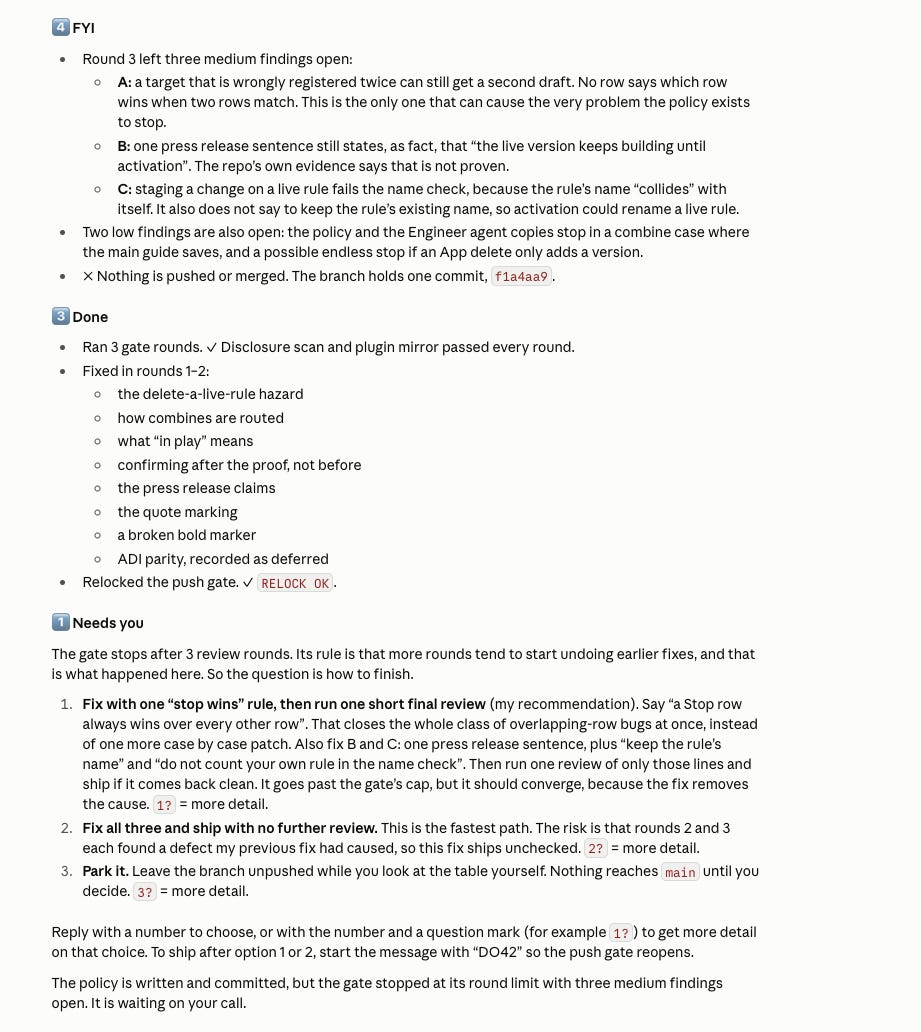
Give automated reviewers a hard round limit before escalating to a human, or they’ll loop forever arguing trivial semantics.
Design for the follower, not the author
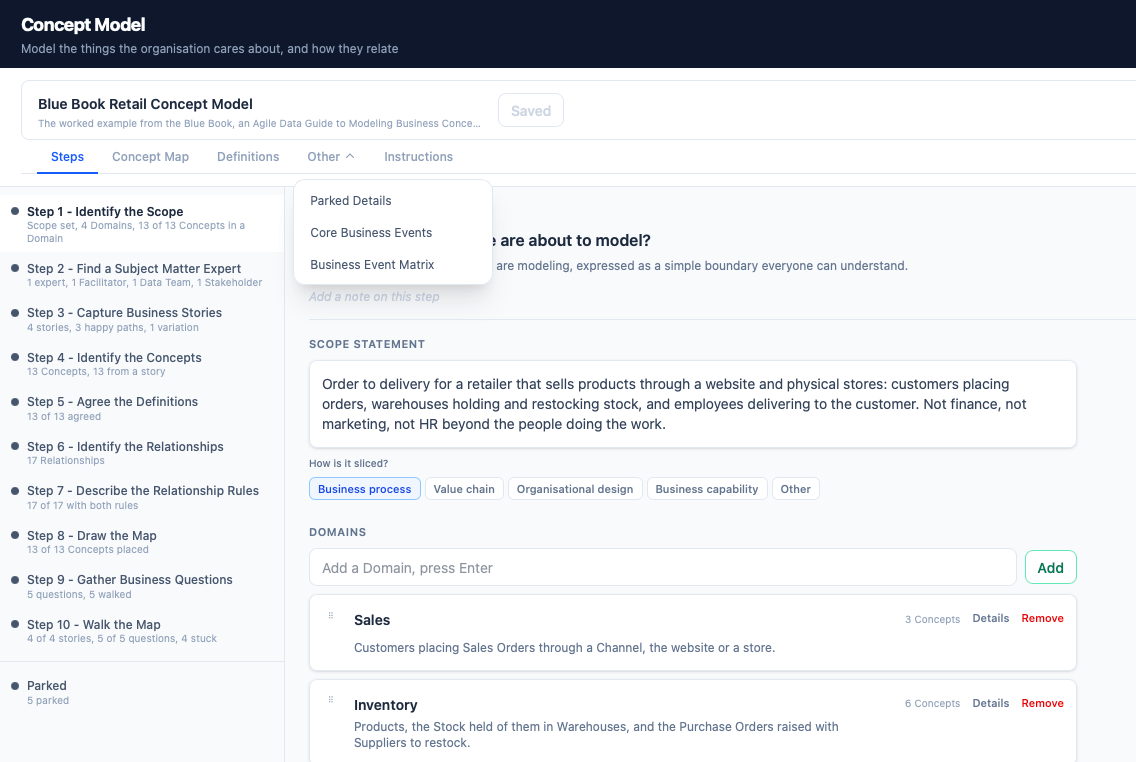
What’s handy for the person who built the pattern can confuse the person just trying to follow the steps - so it belongs in an “other” menu.
Naming sessions to stop accidental deletes
A small naming convention - flagging reviewed sessions - prevents the costly mistake of deleting work that isn’t actually finished.
Consumers want drill-down, not code
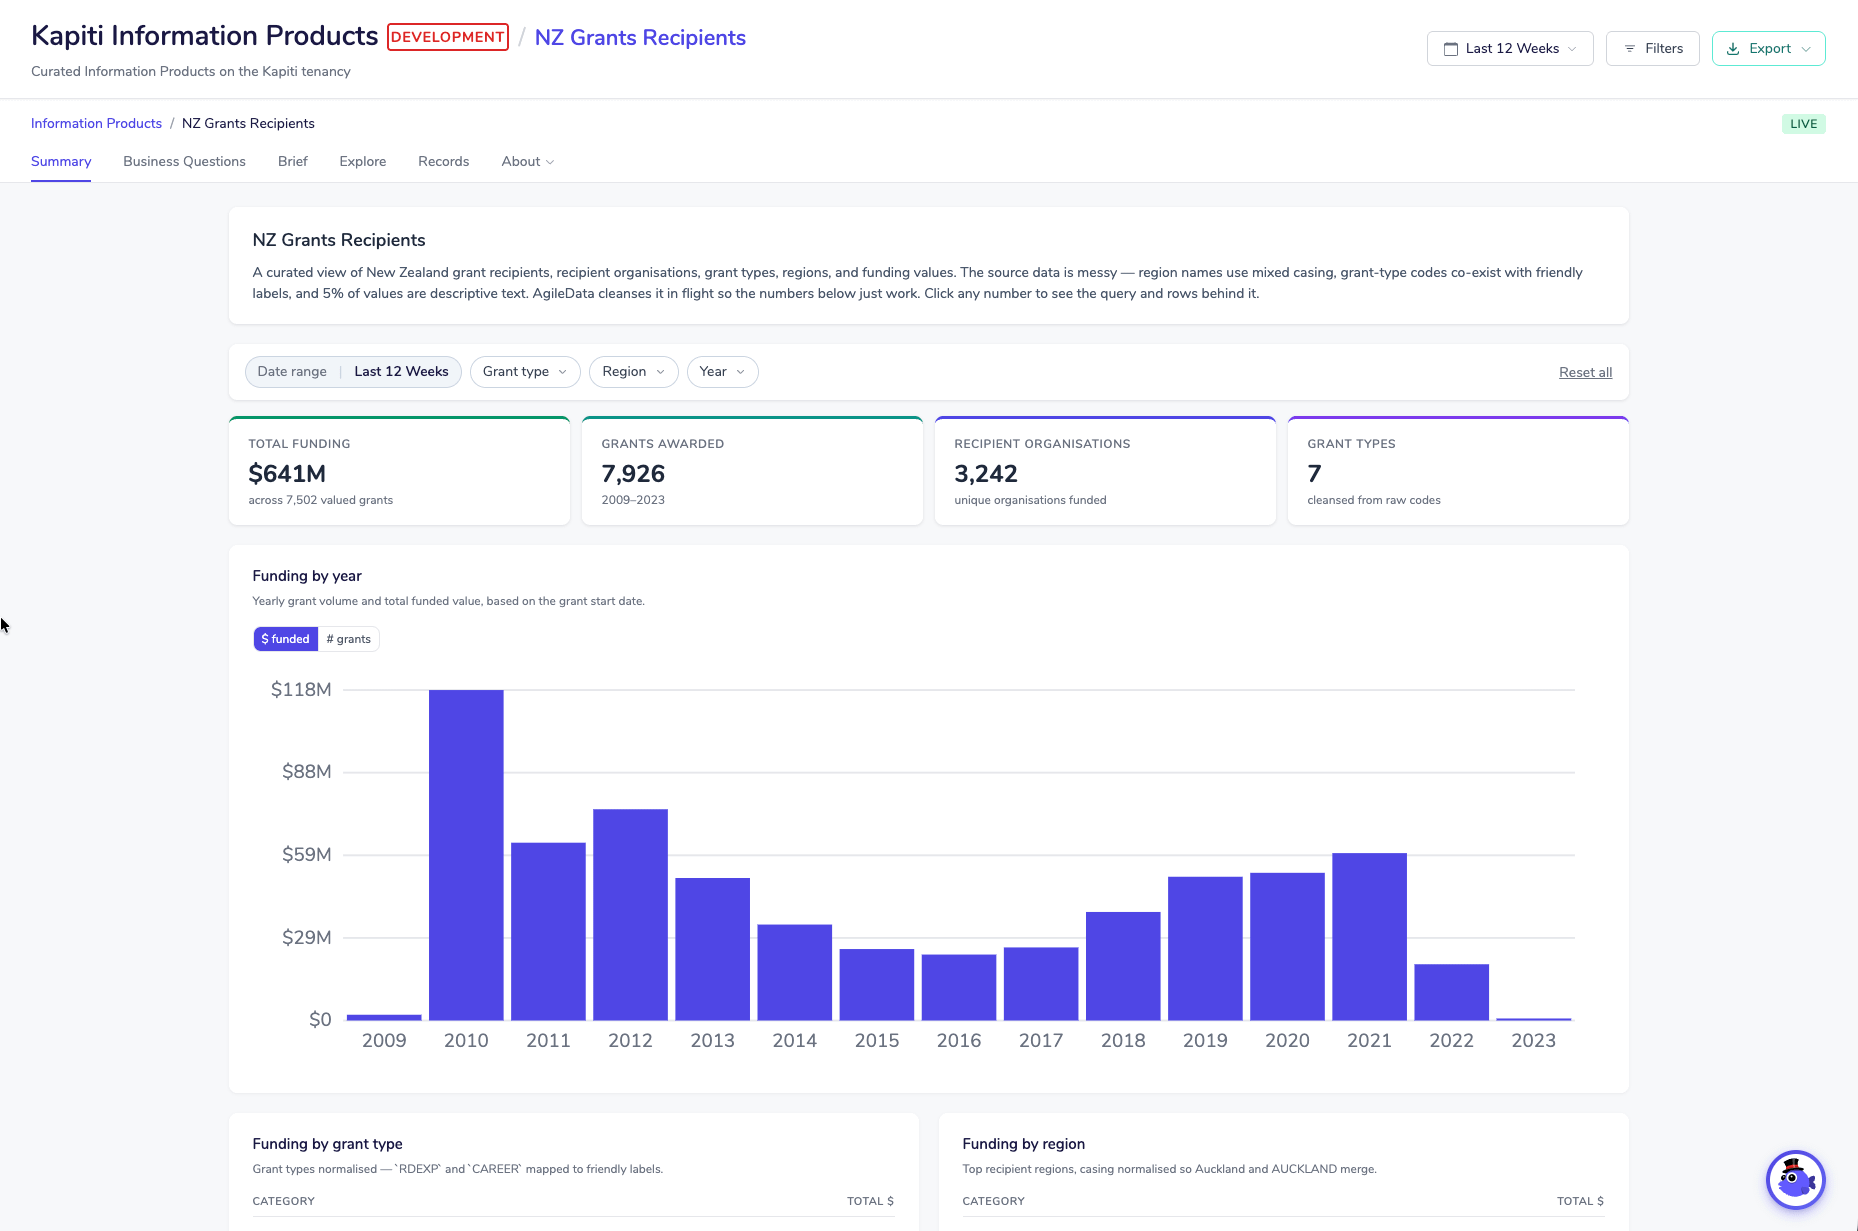
Click a KPI number and consumers expect more detail underneath, not the calculation logic that produced it.
Scolding an AI doesn’t fix terminology
Telling the AI off for using the wrong term didn’t stop it happening again - the fix is a pattern, not a reprimand.
Can GenAI democratise Concept Modeling
A conversation with John Giles and Remco Broekmans on whether GenAI can genuinely open up Concept Modelling - worth a watch.
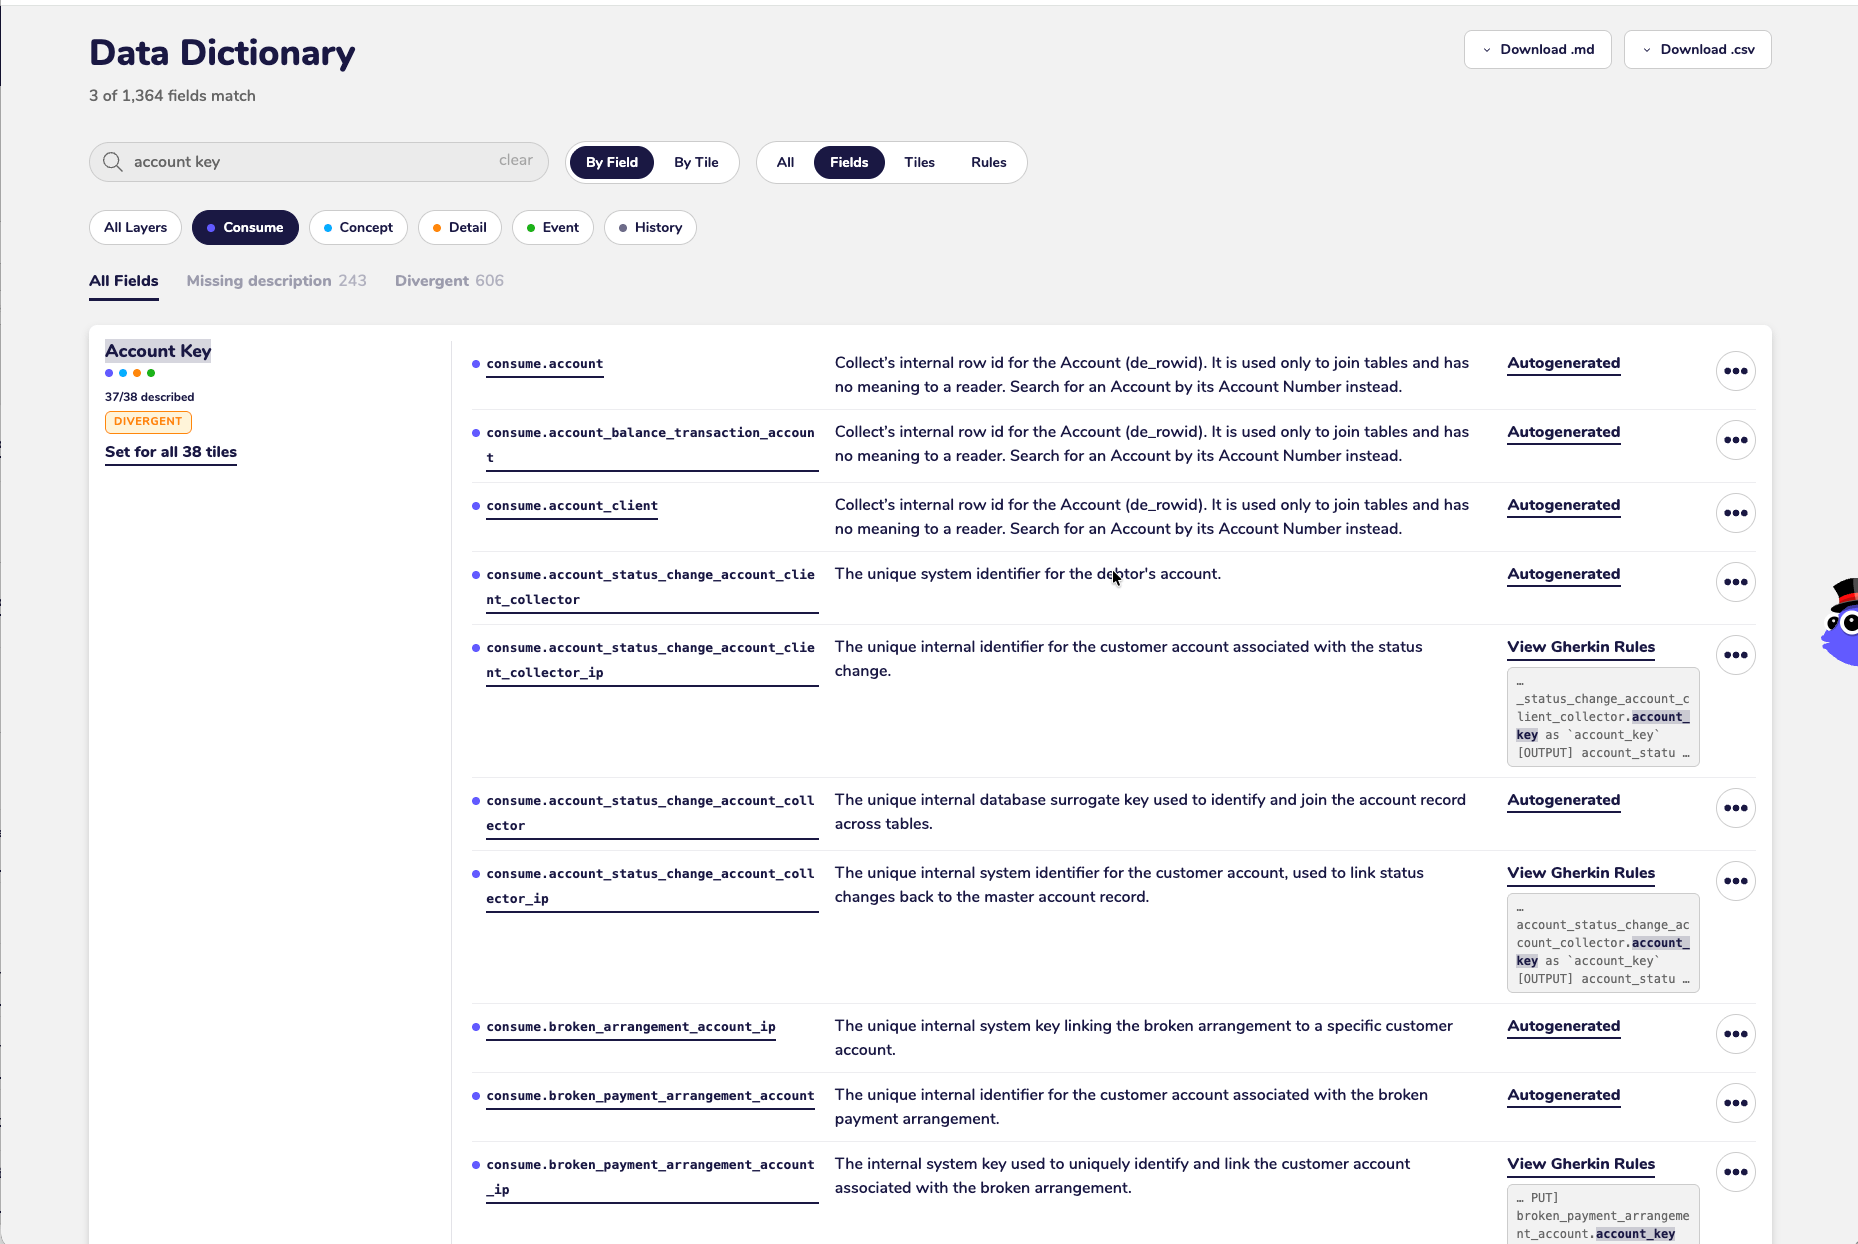
When a shared field’s meaning drifts
The same field name with diverging descriptions across tables confuses even the tools built to help - durable fixes need a glossary, not a patch.
Memes on what makes a dashboard shareable
A meme series, made with AI in the loop, on what a Claude Dashboard needs before it’s useful to anyone but you - following along on LinkedIn.
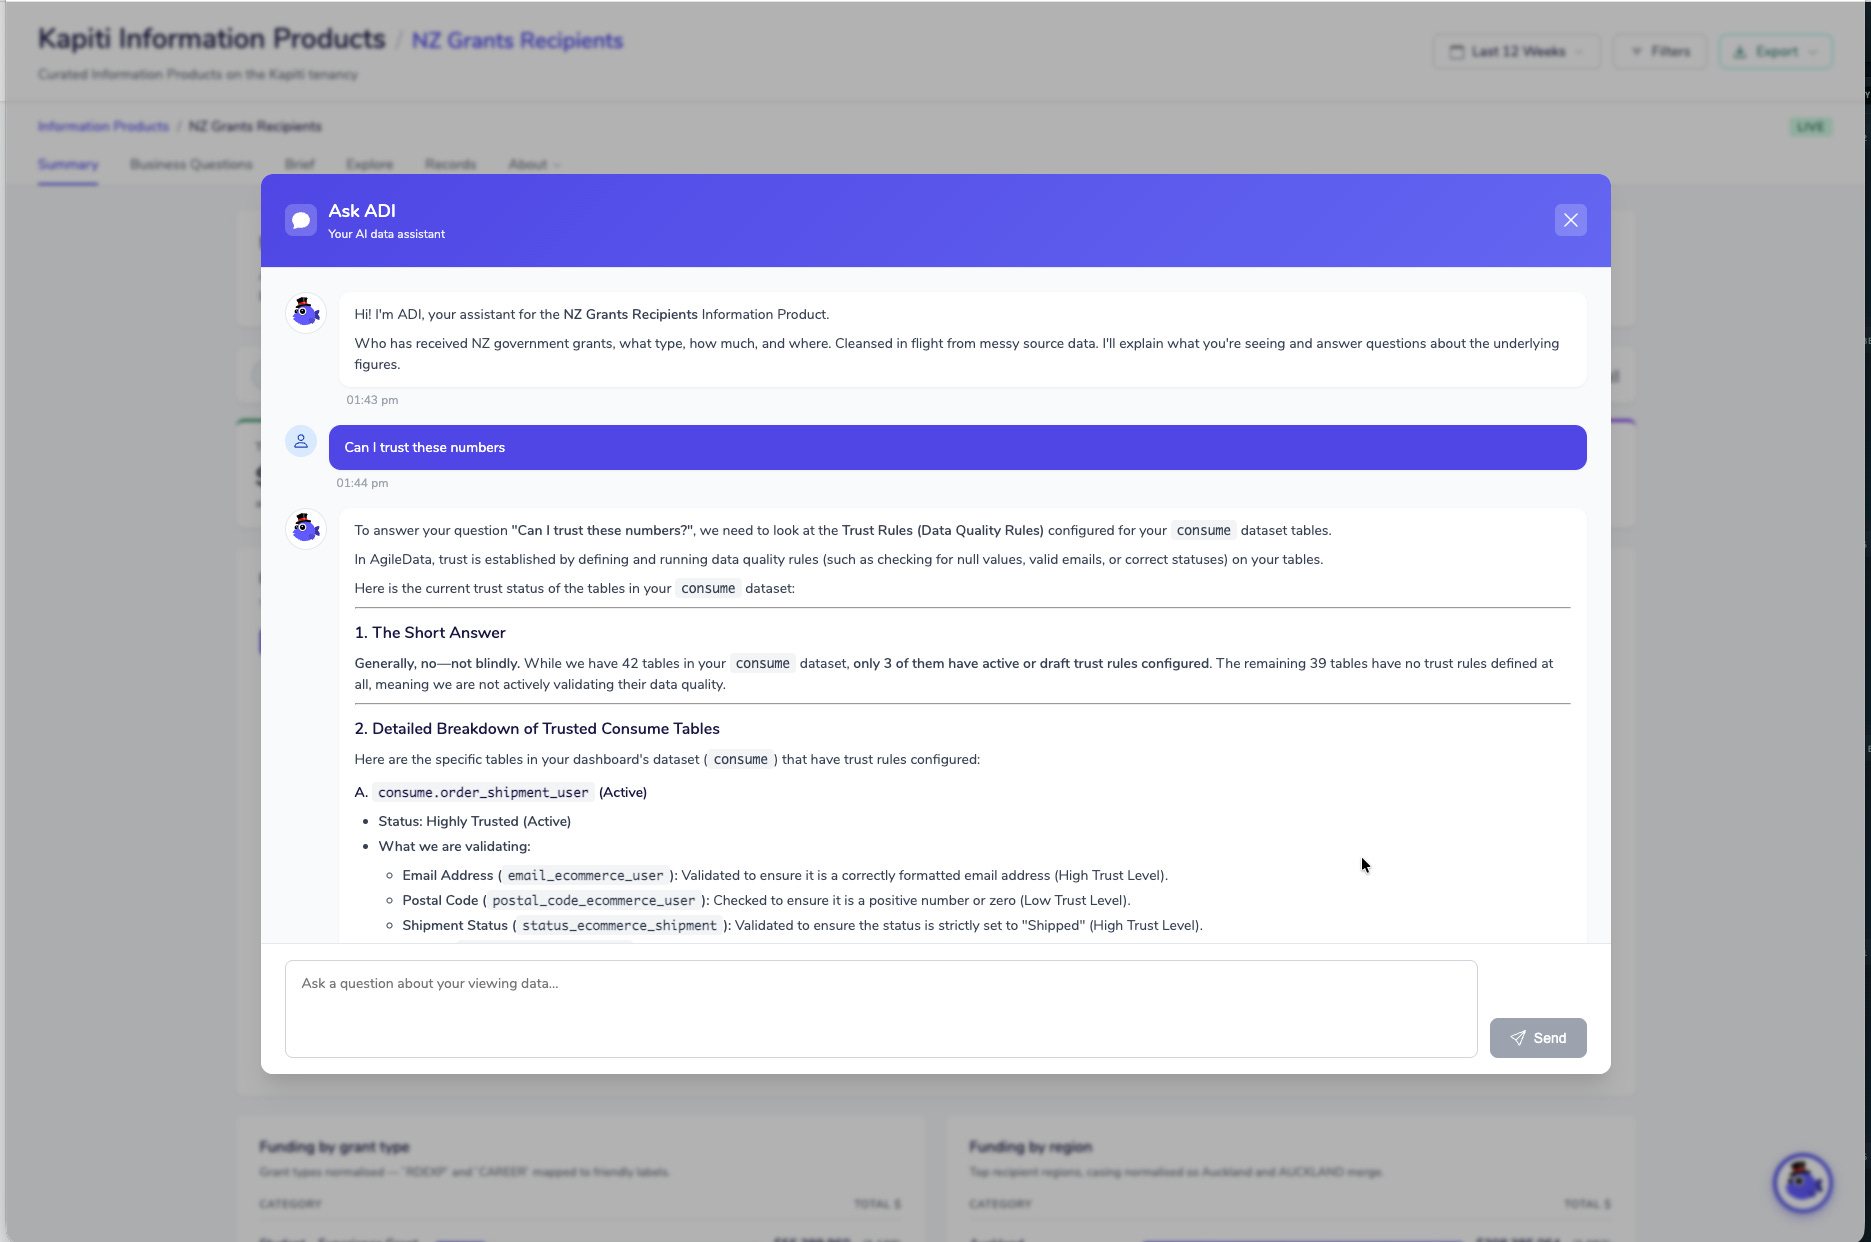
Bind the assistant to what’s on screen
An assistant that answers from your whole dataset instead of the product you’re viewing will mislead you - scope it to the context on screen.
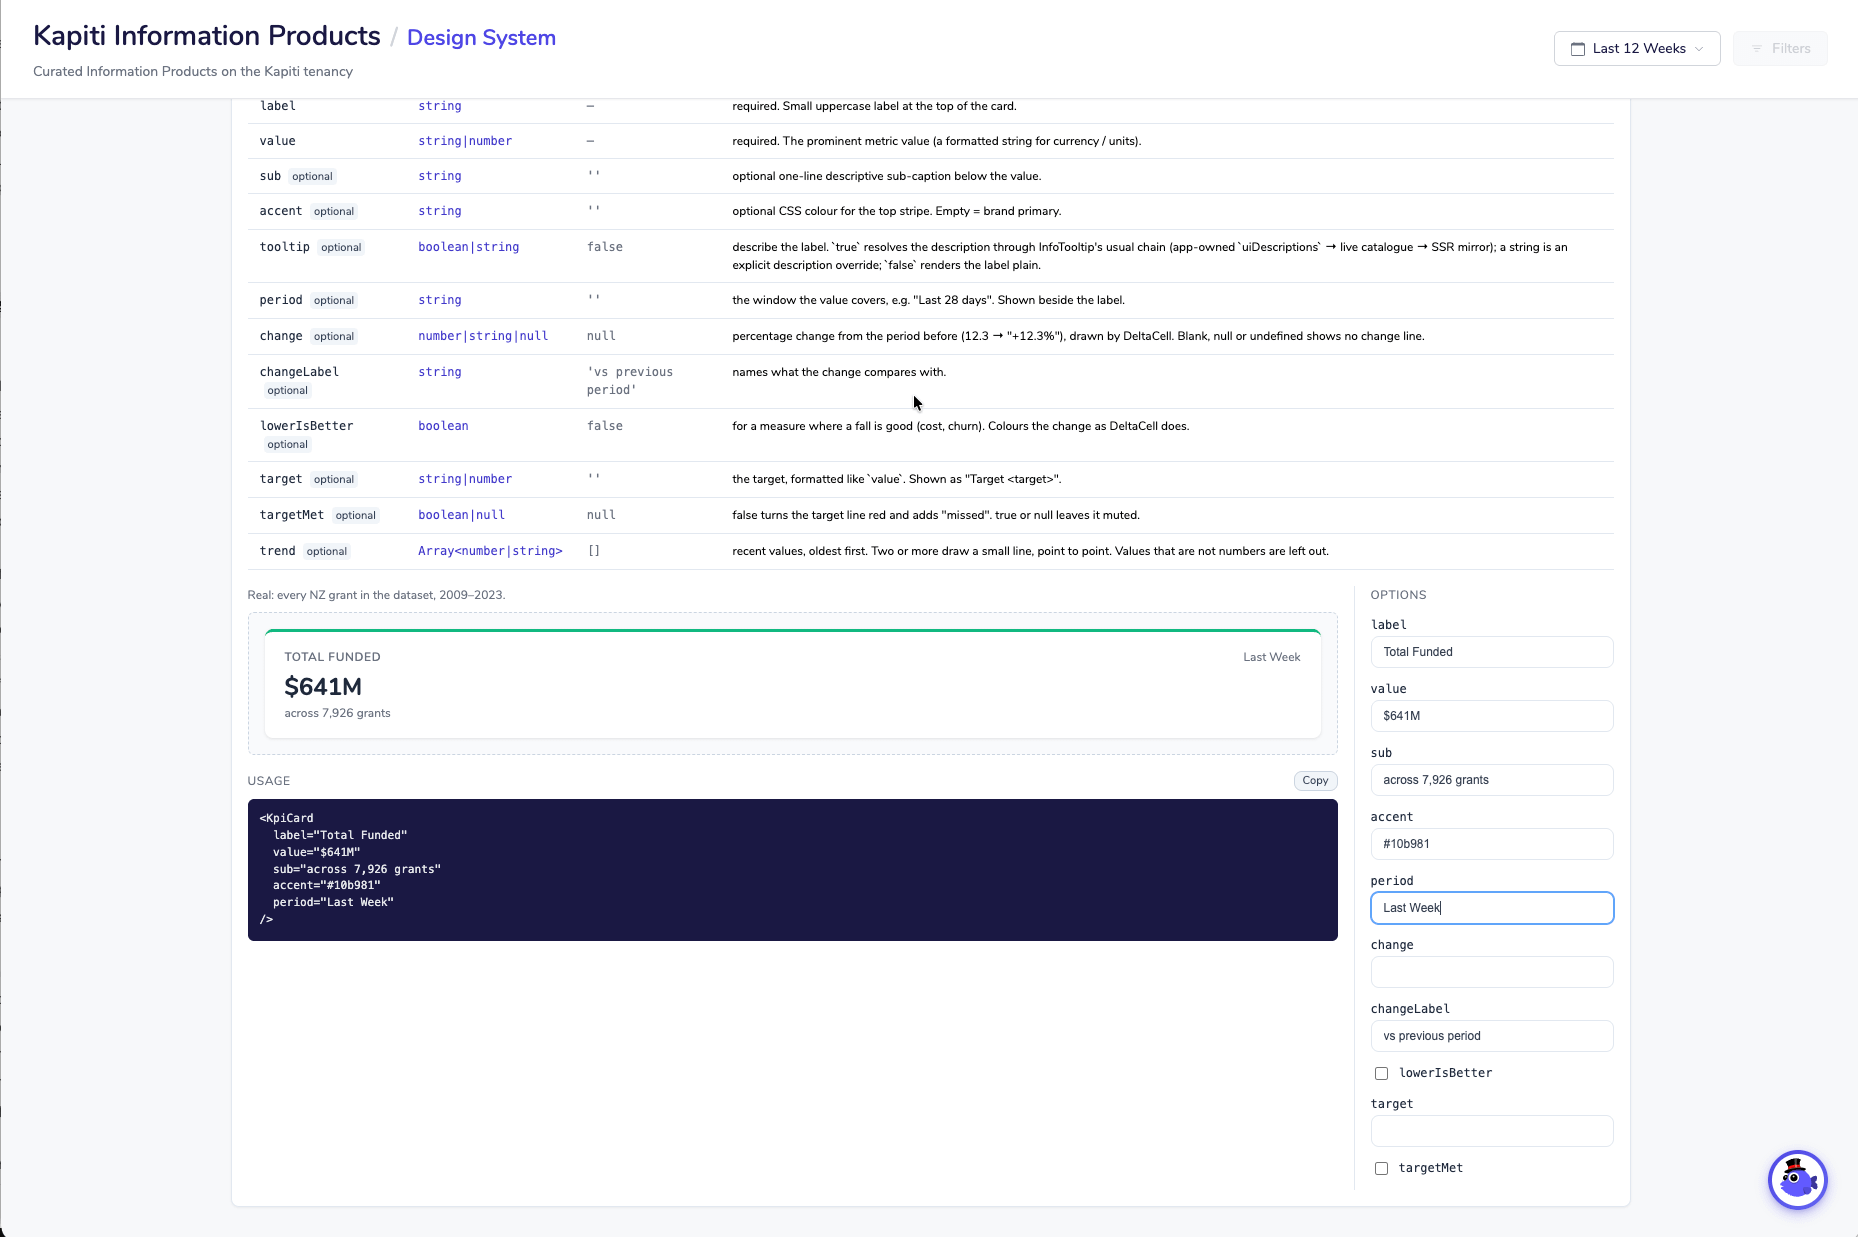
One KPI card hides what six reveal
A new layout feature tested fine with a single component but broke under real density - test at the volume it will actually ship with.
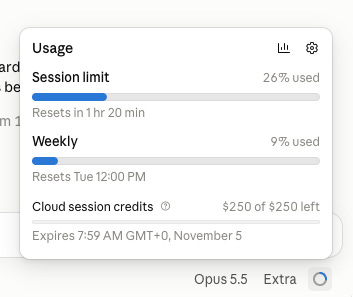
An extra click for Claude’s session stats
Claude’s usage-stats UI now takes two clicks to reach the detail instead of one - worth watching whether hiding the number first helps or hinders.
Mini games as a design discipline
Treating each data-work tool as a small game inside a bigger journey forces real discipline on the shared path and language, which is no bad thing.
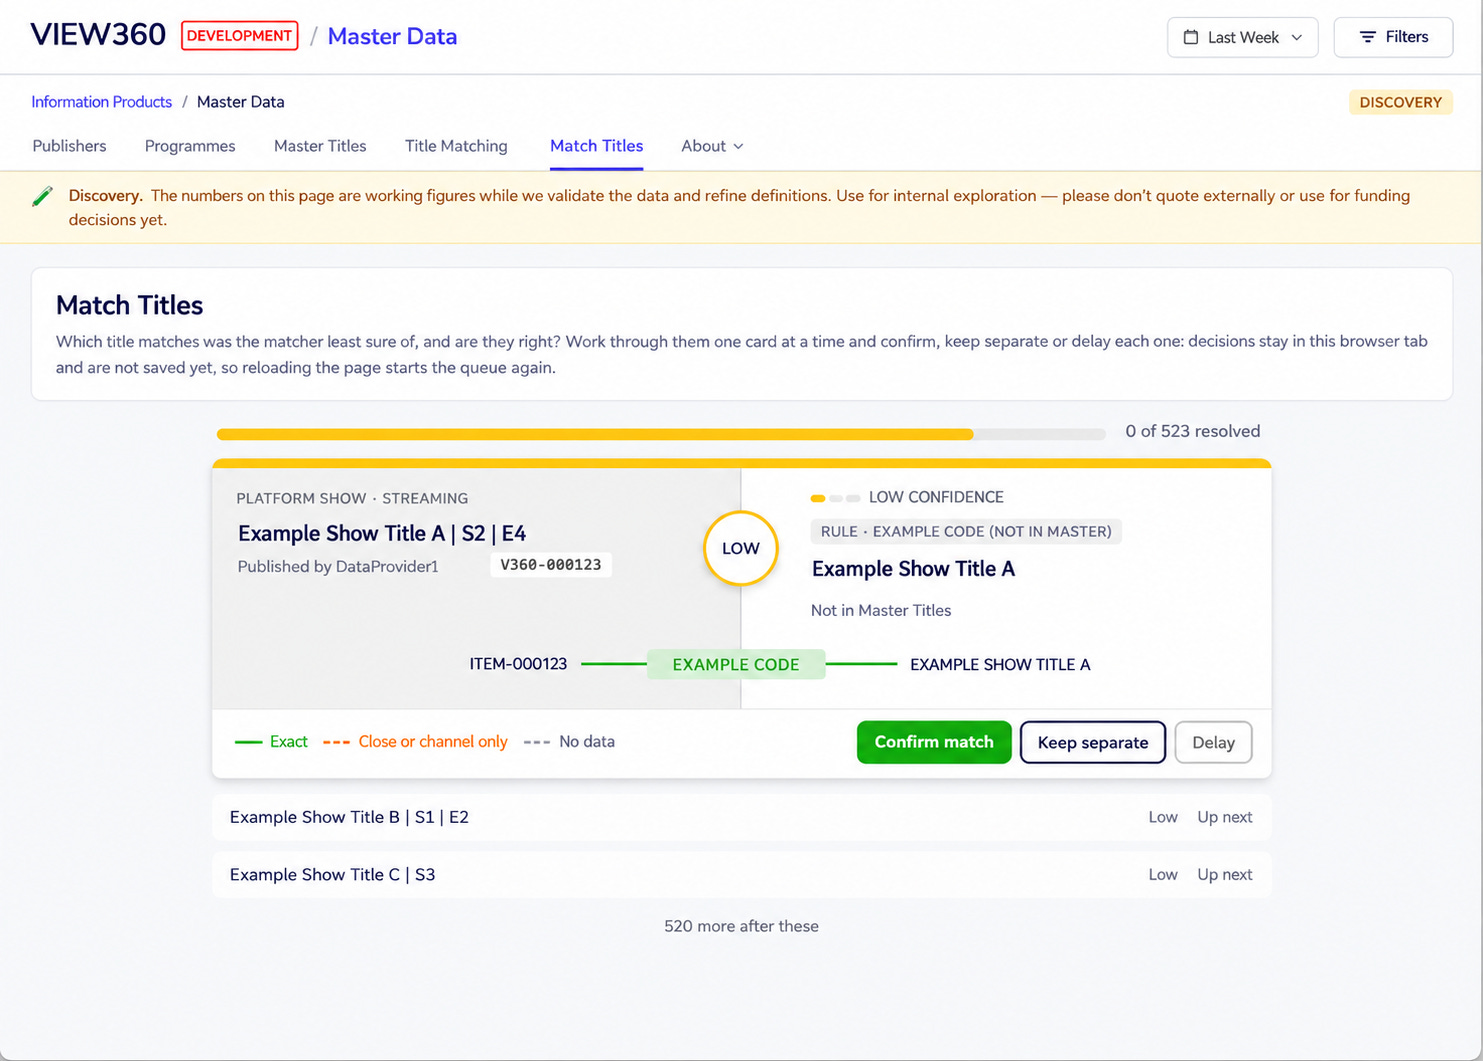
First cut of the Matching Titles app
An early build-in-public look at the new Matching Titles app for MediaView360 - a share, not yet a lesson.
Latest AURA session with Anna Bergevin
This month’s AURA conversation with Anna Bergevin is live - a reminder of how much changes in just a month.